VISUAL PROBABILITY / EXPERIMENT 01
One image encoding.
Several probability queries.
A small trained model reads a synthetic image and its supplied prior. Change the evidence, then ask several questions of the same distribution.
1 Choose the evidence
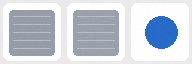
Two views of the same fixed development example. Gray panels hide objects; the supplied prior stays with its example.
Loading the published model…
2 Read a shared distribution
Estimates appear after the model runs.
Model estimates, not certainty guarantees. Each answer uses the same distribution over 64 possible scenes.
REUSE THE DISTRIBUTION
Ask another event question.
Changing the question does not rerun the image encoder.
What this demo establishes — and what it doesn't
This is a live ONNX export of the published synthetic-joint seed-17 CNN, including its temperature calibration. Inference runs on your device. The two images are fixed development views, not selected test successes.
The scene vocabulary has three positions, two colors and two shapes. Queries combine red, blue, circle, square, same_color, same_shape, and, or and not. They use explicit semantics, not learned free-form language understanding.
The full project has separate DINOv2-based Pets and CLEVR-4 experiments. Published failures include degradation on new dependency structures and better unseen-combination generalization from independent attributes than from the tested joint and binding heads.
Export provenance and verification · Complete experiment results